

This is part of a three post series - check out my thinking on using local AI, rather than sending it all to cloud-frontier models and using AI to assist, not takeover.
Cut to the chase and get the extension here from the Git Repo. I currently pending Chrome Extension store acceptance.
The most useful way to think about this extension is more like a tech SEO workbench inside the browser. It has most-common SEO issues checked and then you can use a local LLM (Gemini Nano) to help triage small issues or summarise the data for more complex ones. Should you want to speed up the process, you can also add in your own API keys for OpenAI or Gemini too.
The main goal
The aim is to reduce the number of times you need to leave the page, open another crawler, paste something into a spreadsheet, start a separate AI conversation or manually assemble evidence before you can investigate something. It’s also not a case of delegating everything to an AI Agent and submitting work on “trust”.
That makes it (I hope) particularly useful during the messier parts of technical work: QA’ing, detailed spot checks, development reviews and investigating pages where you think something doesn’t look right.
This extension is still in an early testing phase, but I wanted to share to gain feedback and share this as a proof-of-concept, as I think there’s a lot of merit to approaching issues like this.
Using Nano SEO Lab
The normal starting point is a full-page analysis (under Overview).
Without you needing to do anything aside from open the extension, it reads the current page and runs a set of deterministic checks across things such as:
titles and headings
canonical and indexability signals
links
images
structured data
URL and locale declarations
differences between server HTML and the rendered DOM
Those checks are deliberately kept separate from model judgement.
The first question should be:
What can we actually observe about this page?
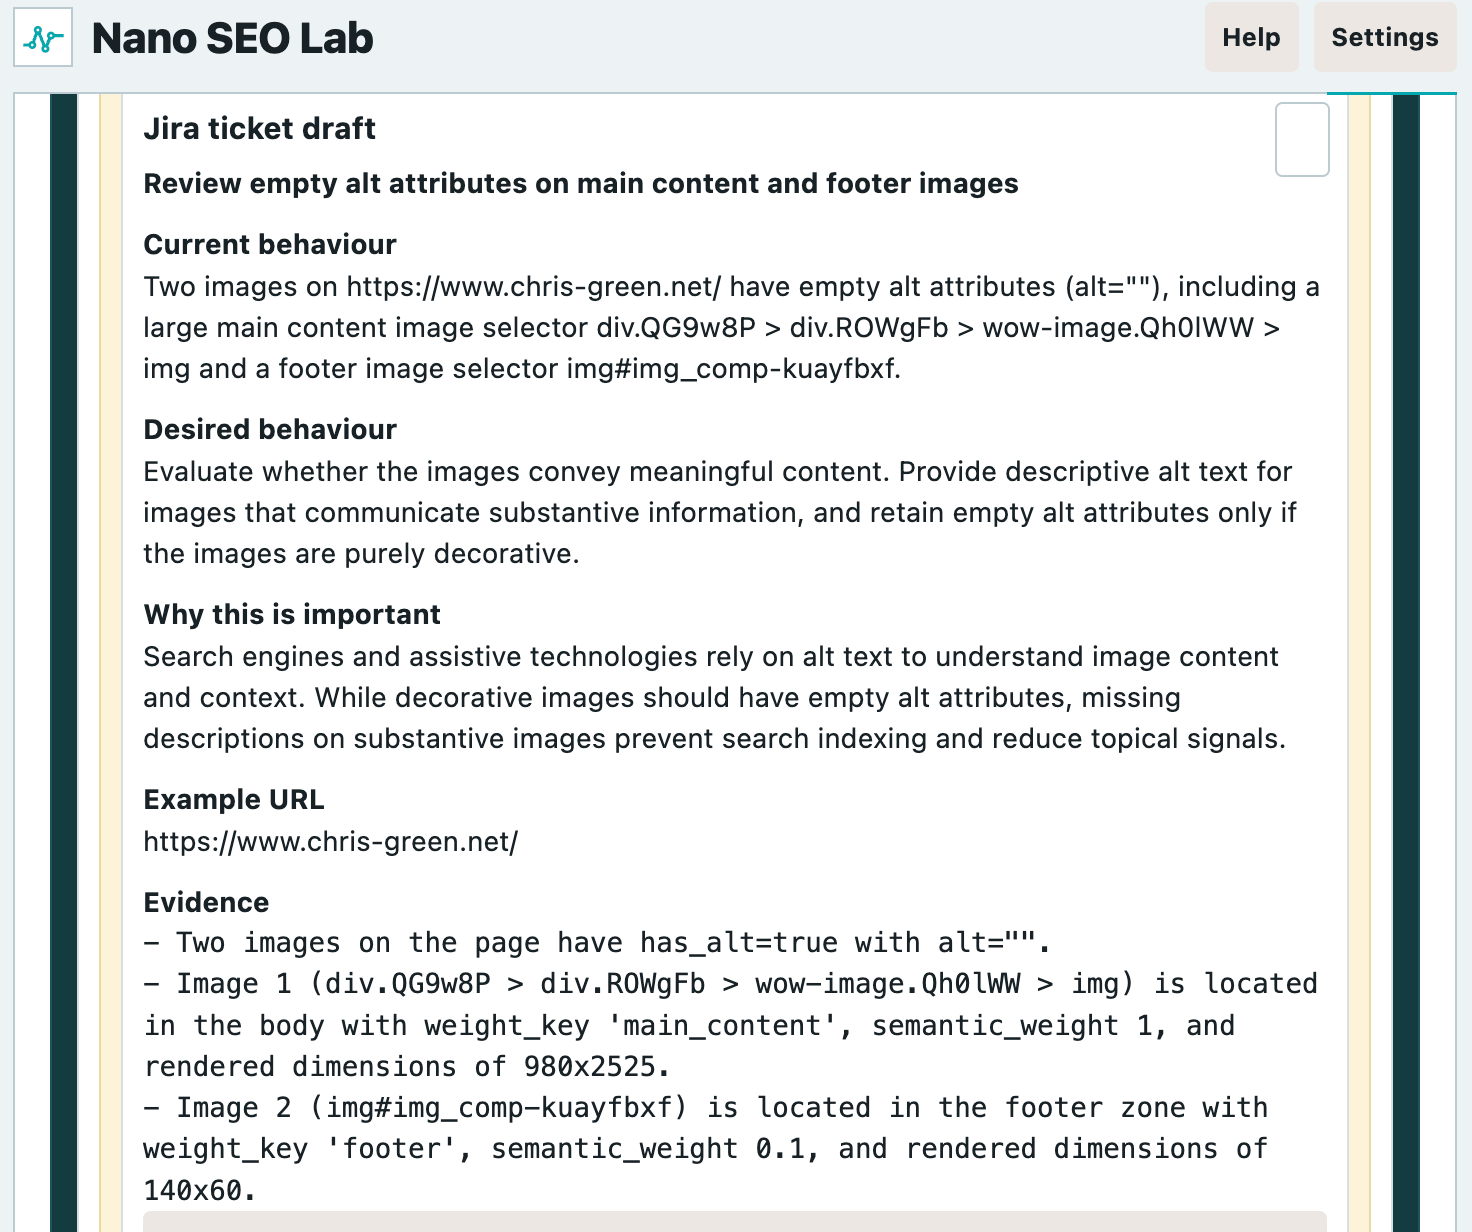
You can then use the model (Nano, Gemini or OpenAI) to triage the issue, if you think it’s needed, and then use the tool context to write a Jira Ticket ready to copy and paste in.
To use Gemini/OpenAI, click “settings” and enter in your API keys under “Providers and page permissions”
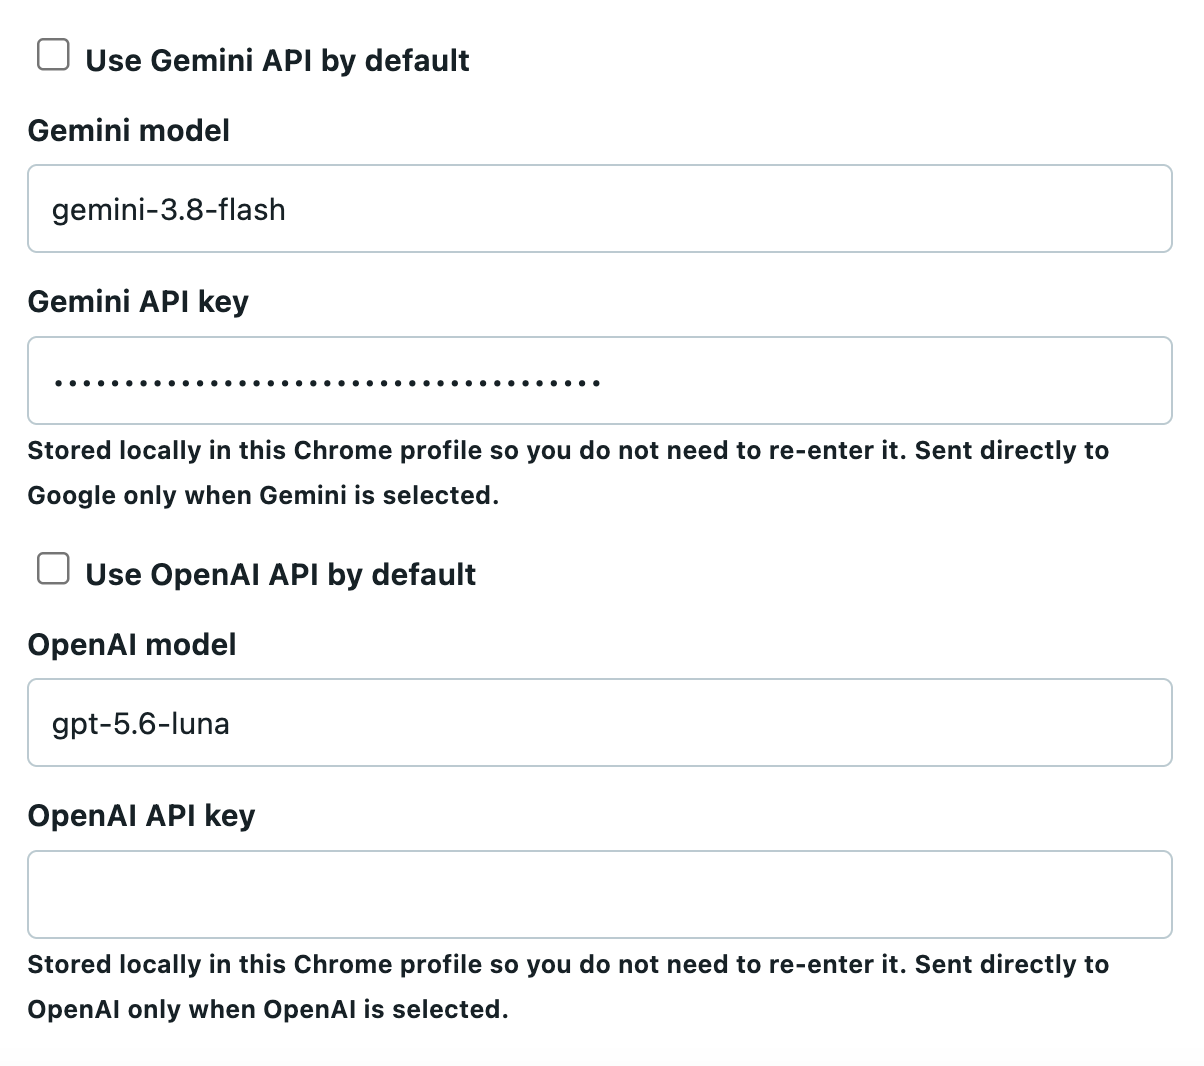
If you decide you always want to default to one of these models and bypass Nano, you can.
Keep the evidence visible
The main thing I wanted to ensure was that the underlying evidence is inspectable.
If the extension says a URL changed after rendering, you should be able to see the original URL and the rendered URL.
If a link returns a 404, you should be able to see the requested URL, status and final destination.
If the server and rendered DOM differ, you should be able to inspect what changed rather than simply accepting that the model thinks something “looks significant”.
The model output should sit on top of that evidence, not replace it.
Use models where interpretation is actually useful
Where models become most useful is when the facts need context. Read more on my thinking here.
For example, the DOM comparison can identify differences between the server HTML and the rendered page, reconcile those differences and remove obvious implementation noise such as hydration/state/cache IDs where the actual semantic value hasn’t changed.
The comparison summarises things such as:
how many meaningful differences were detected
how many may benefit from model review
how much obvious implementation noise was removed
how much of the comparable page inventory appears to have changed
The reviewable differences are then split into explicit batches, mostly because Nano has a limited context window, but also because you may not want to send everything all the time.
You can review any batch independently and you can always inspect the underlying difference before deciding whether the model’s interpretation is useful.
A quick tour of the tabs
Once the main page analysis has run, the other tabs are mostly there to let you investigate particular questions in more detail.
Overview
This is the main starting point.
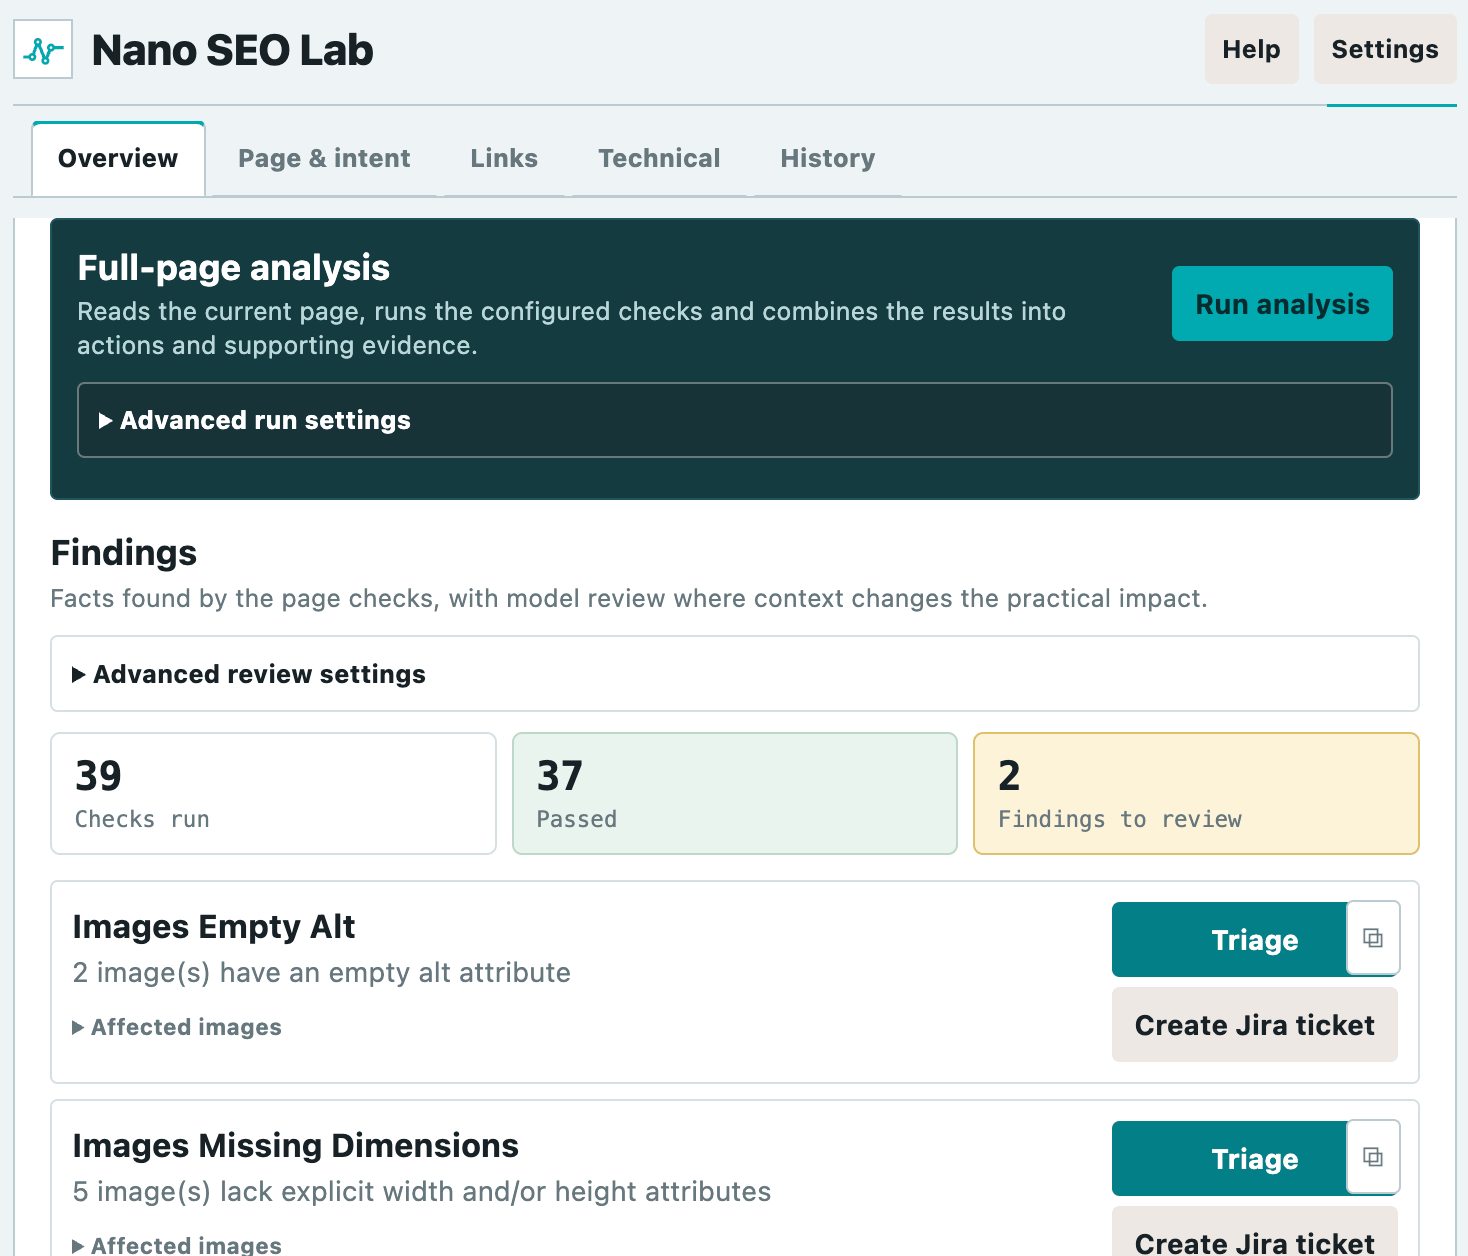
Run analysis reads the page, runs the configured checks and brings the results together into findings, passed checks and supporting evidence.
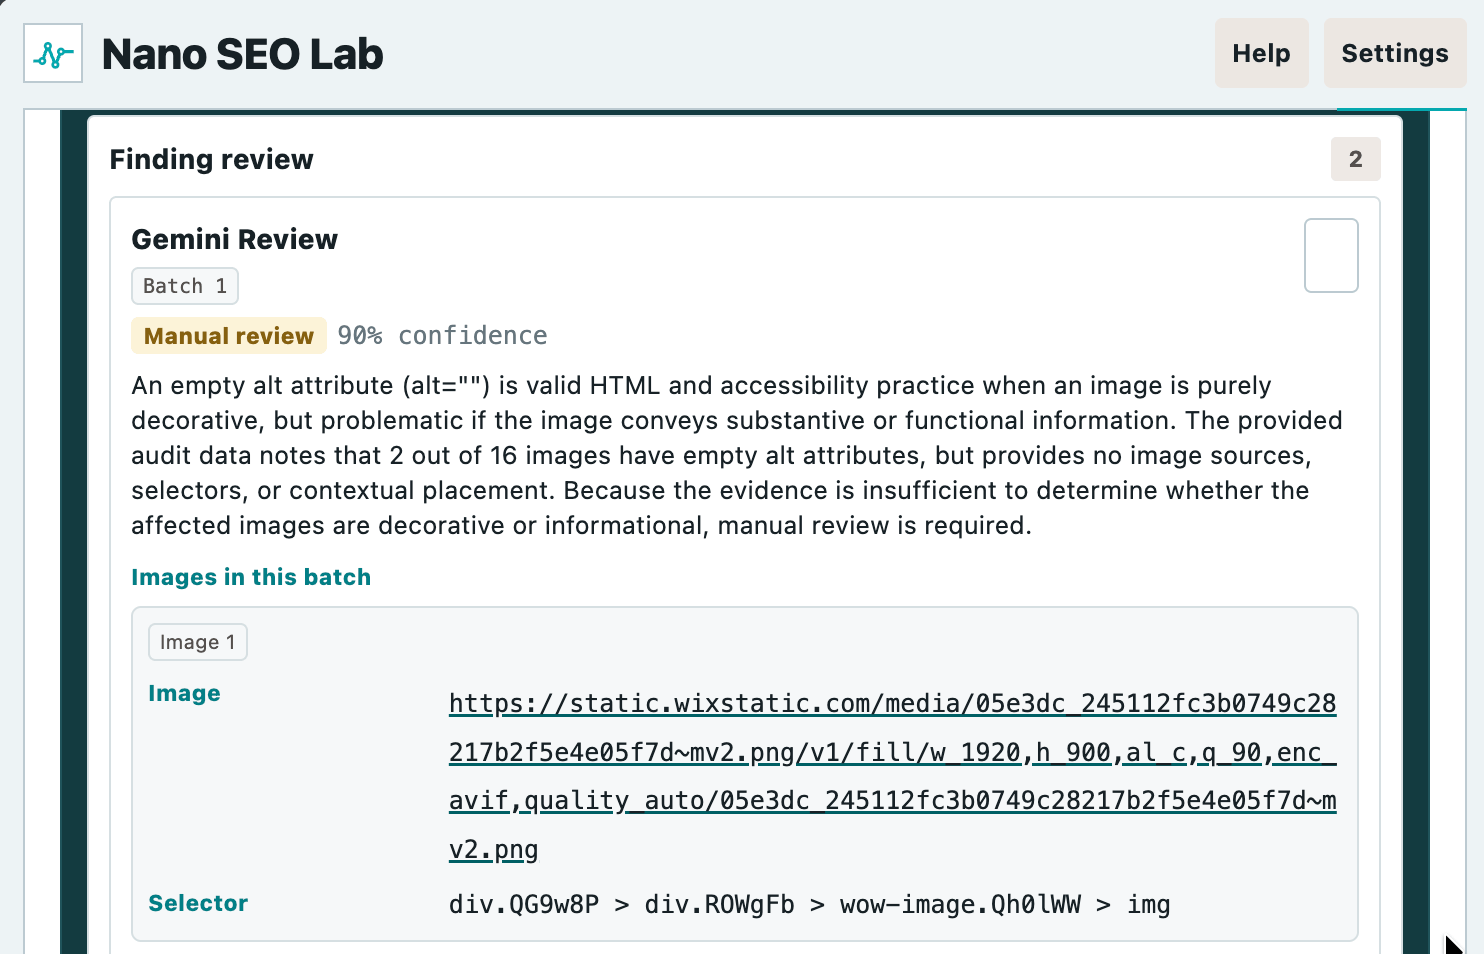
For each finding you can inspect what was detected and, where useful, ask one of the selected models to review the context. In the below example, Gemini couldn’t tell, so rather than guess, t provides the detail for you to make the final call.
This is also where you can turn a finding into a draft Jira ticket once you’ve decided it is something worth acting on.
There are some advanced controls for things such as how many links, examples or DOM differences are sent in each model call, but the defaults should normally be fine.
The useful bit here is simply getting a broad view of the page before deciding which areas deserve a closer look.
Page & intent
This tab is for asking:
What kind of page is this, what is it trying to satisfy, and do those things line up?
The main action is Review alignment.
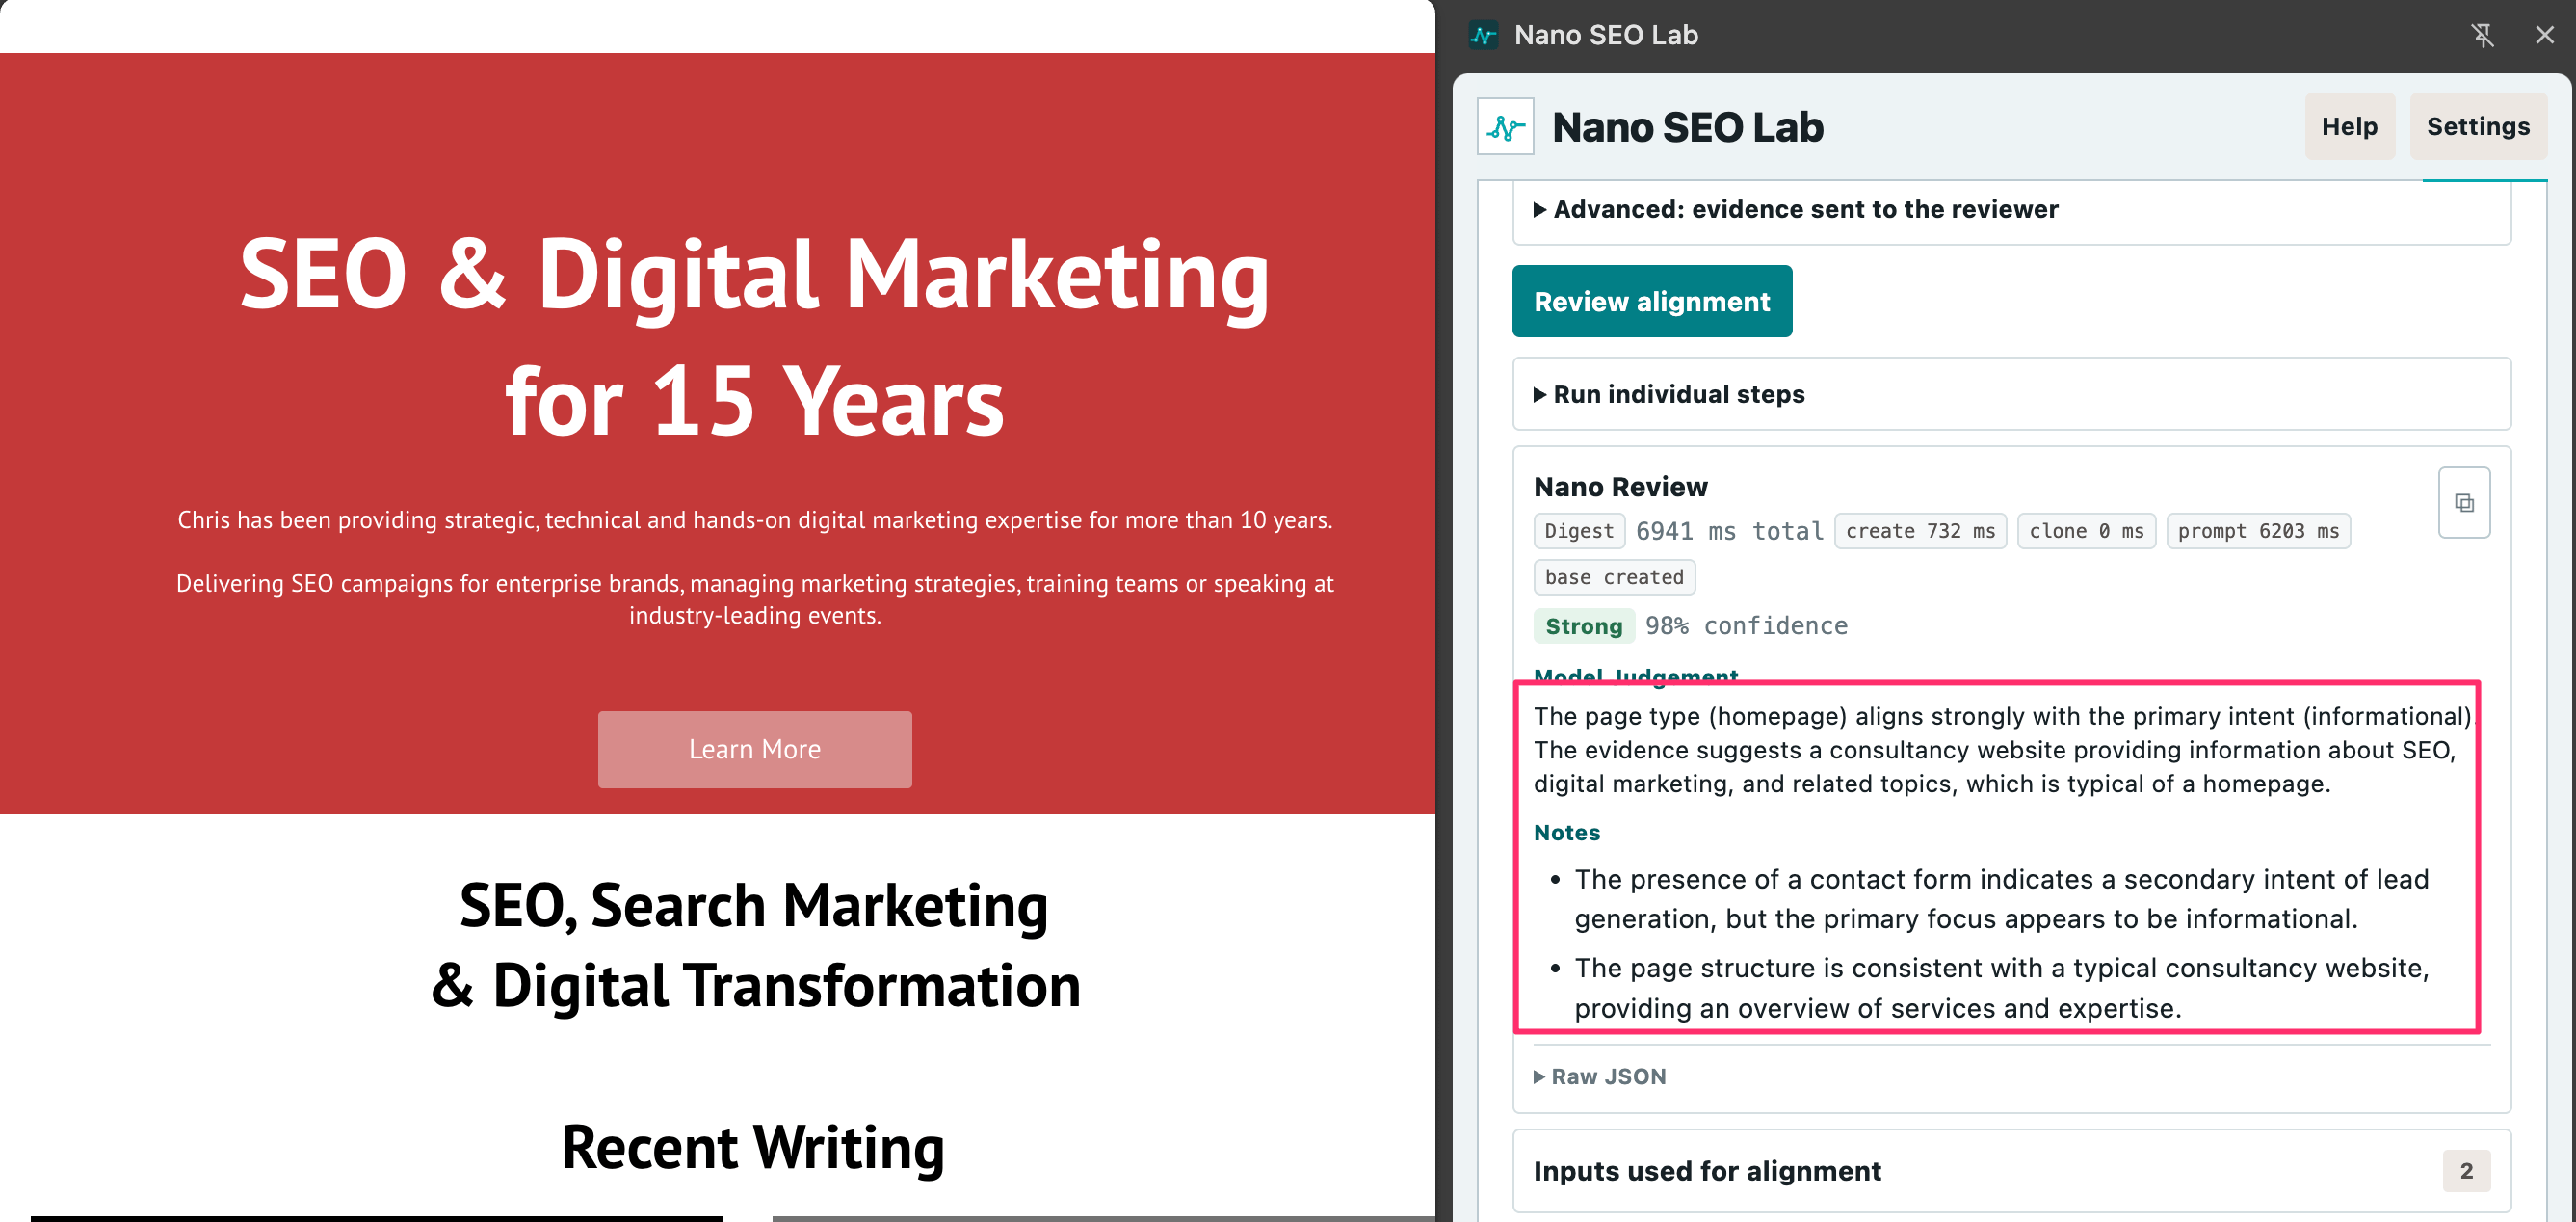
That runs the process in sequence:
identify the page type
identify the likely intent
review how well the two align
You can still inspect the page-type and intent outputs separately, and there are individual buttons if you only want to run one part of the process.
There is also an advanced option to change what representation of the page is sent to the model.
By default I’d leave it on the structured digest, but you can also try:
clean HTML
clean Markdown
visible page text
rendered HTML
all five representations for comparison
That last option is particularly useful for testing how much the representation itself changes the model’s judgement. Use this if you’re getting mixed/inconsistent results in case the format the model receives is the problem.
Links
The Links tab is useful when you want to understand more than simply whether a page has links.
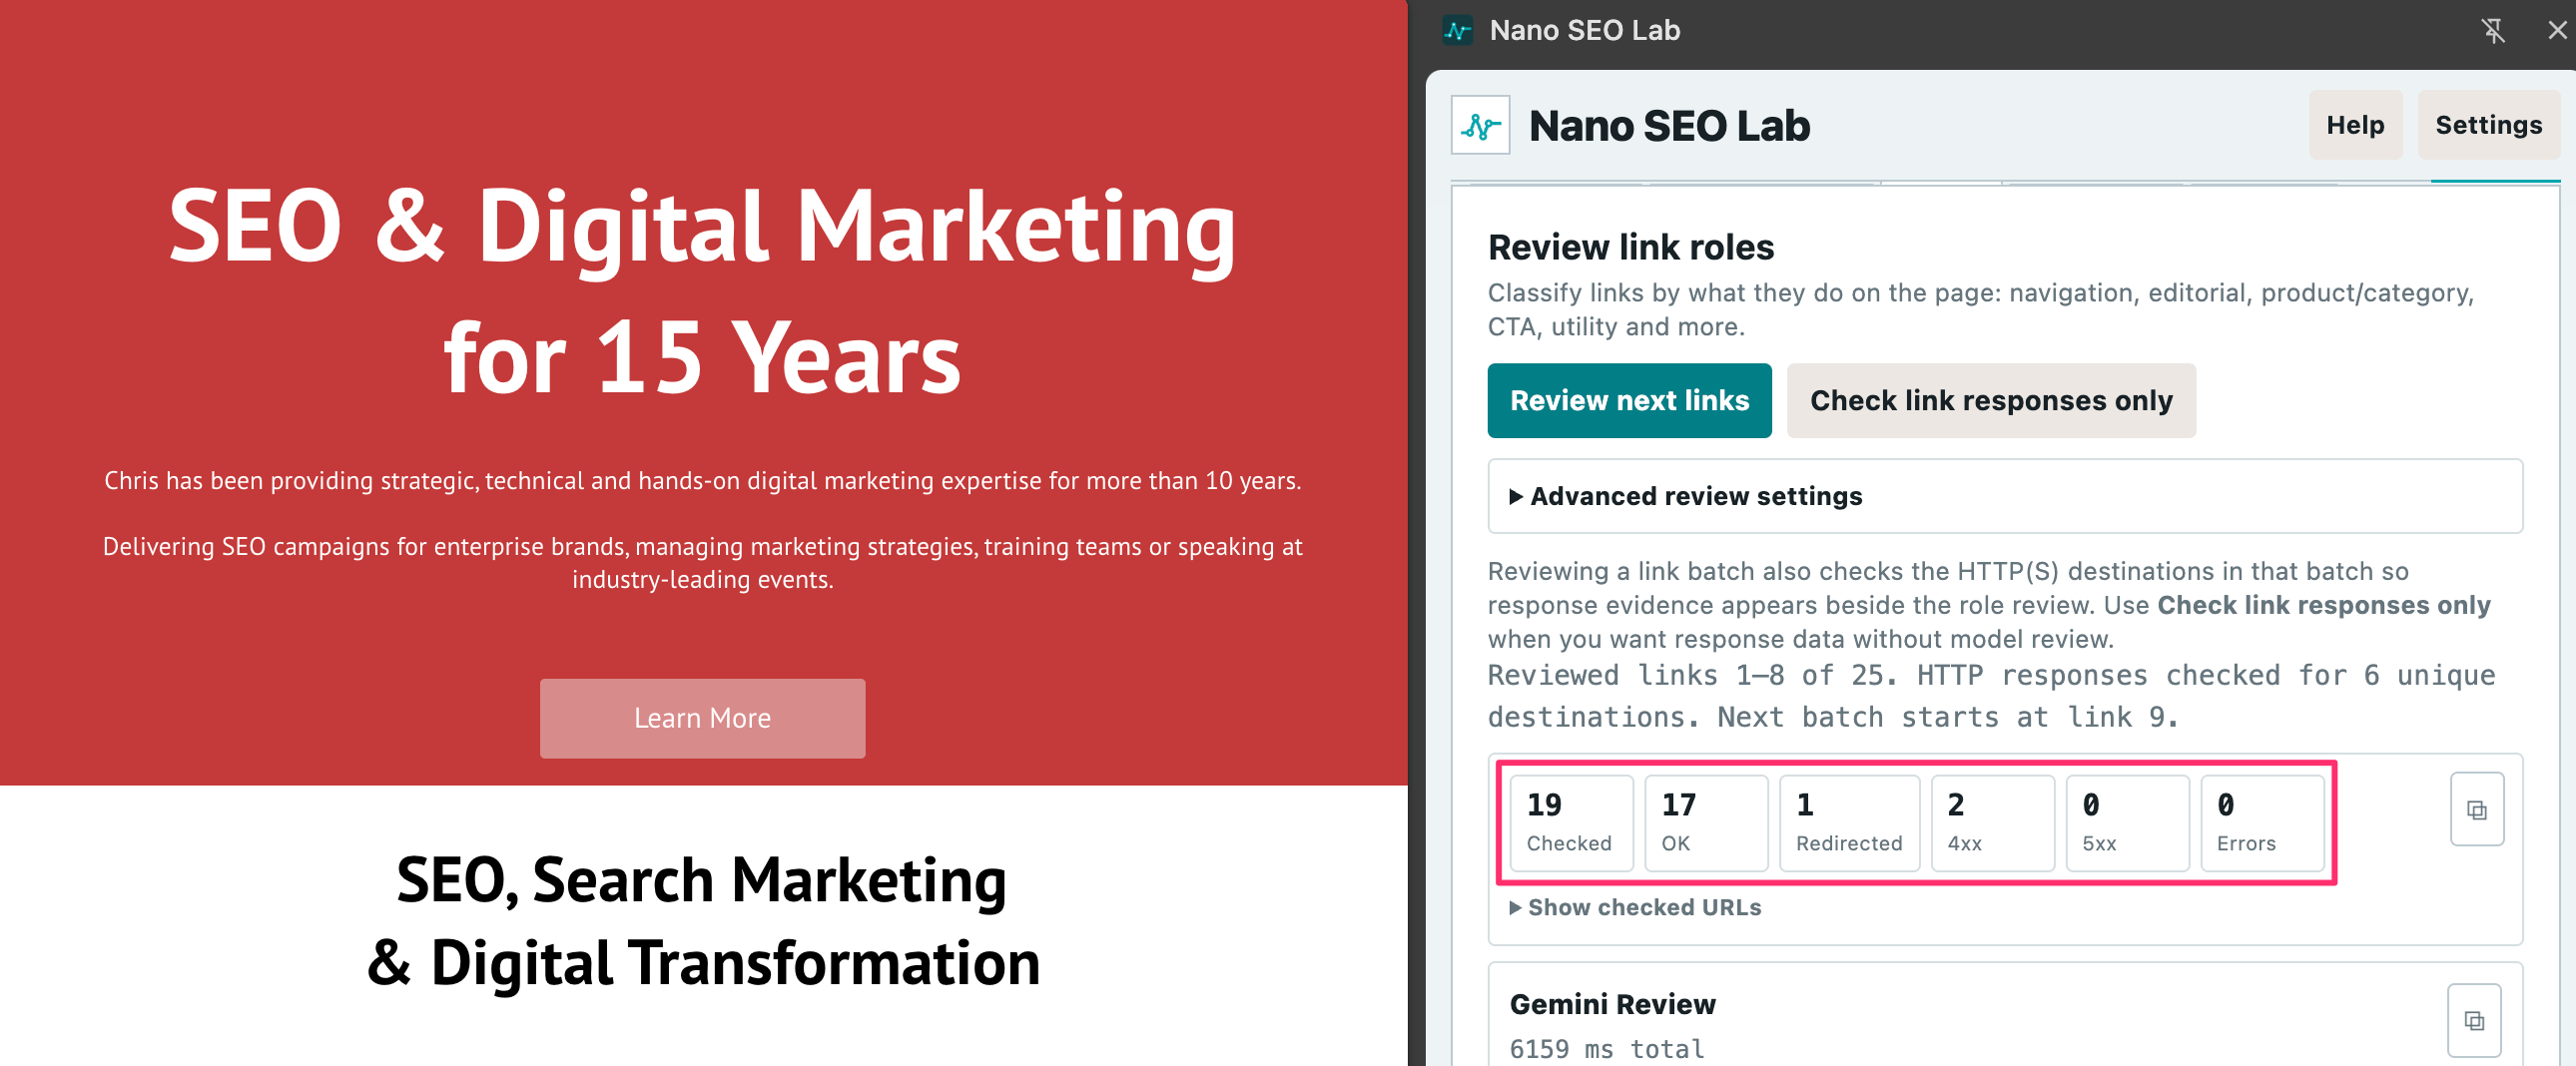
Review next links takes a batch and looks at what those links appear to be doing on the page, for example:
navigation
editorial links
product/category links
CTAs
utility links
At the same time, it checks the HTTP response for those destinations so you can see the role of the link alongside what actually happens when it is requested.
That means you can spot things such as a prominent CTA pointing through redirects or ending in an error without having to run a separate check.
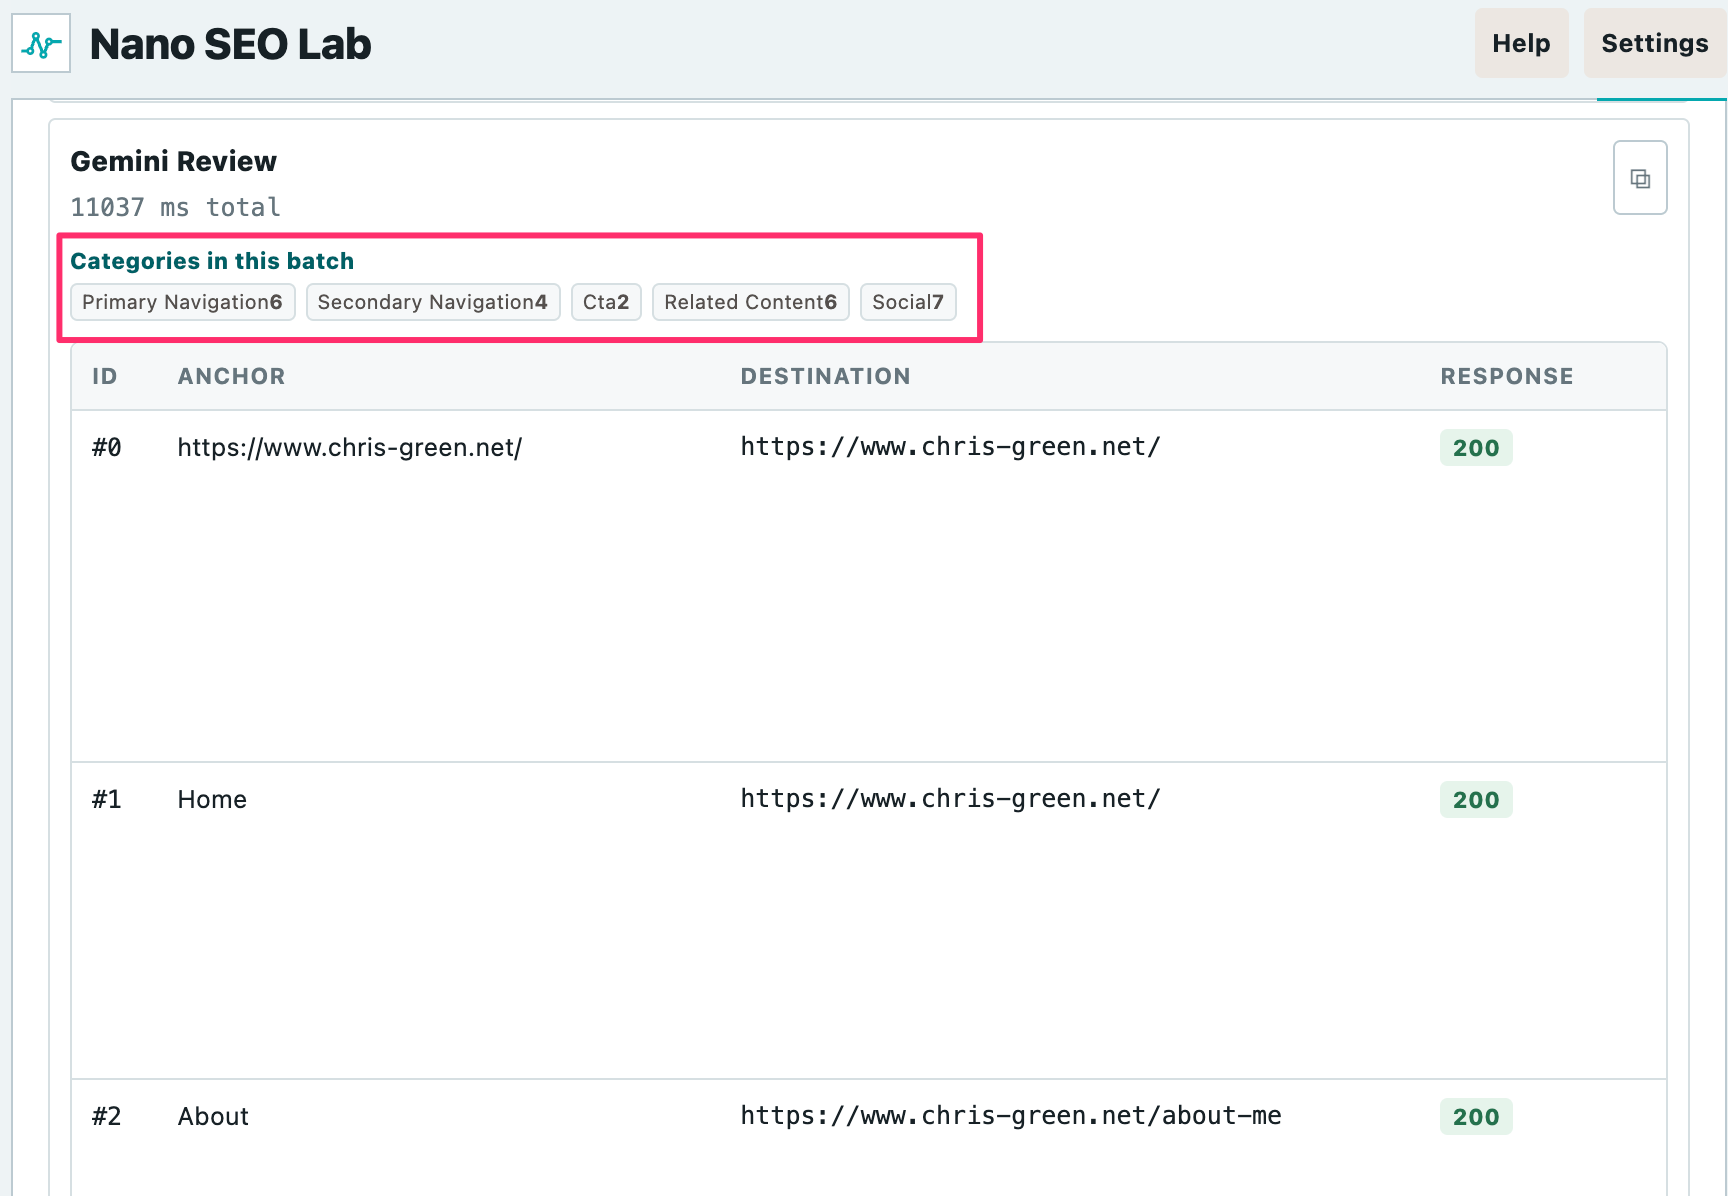
If you don’t want any model interpretation, Check link responses only just gets the response information without judgement/summary.
You can also change the number of links sent in each model call. Smaller batches are generally more suitable for Nano, while Gemini and OpenAI can usually cope with more. If you have a page with a lot of links, you may have an issue running a large batch if the CDN/Bot management kicks in.
Technical
This is where most of the deeper investigation tools live.
DOM comparison
Run comparison compares the server HTML with the live rendered DOM.
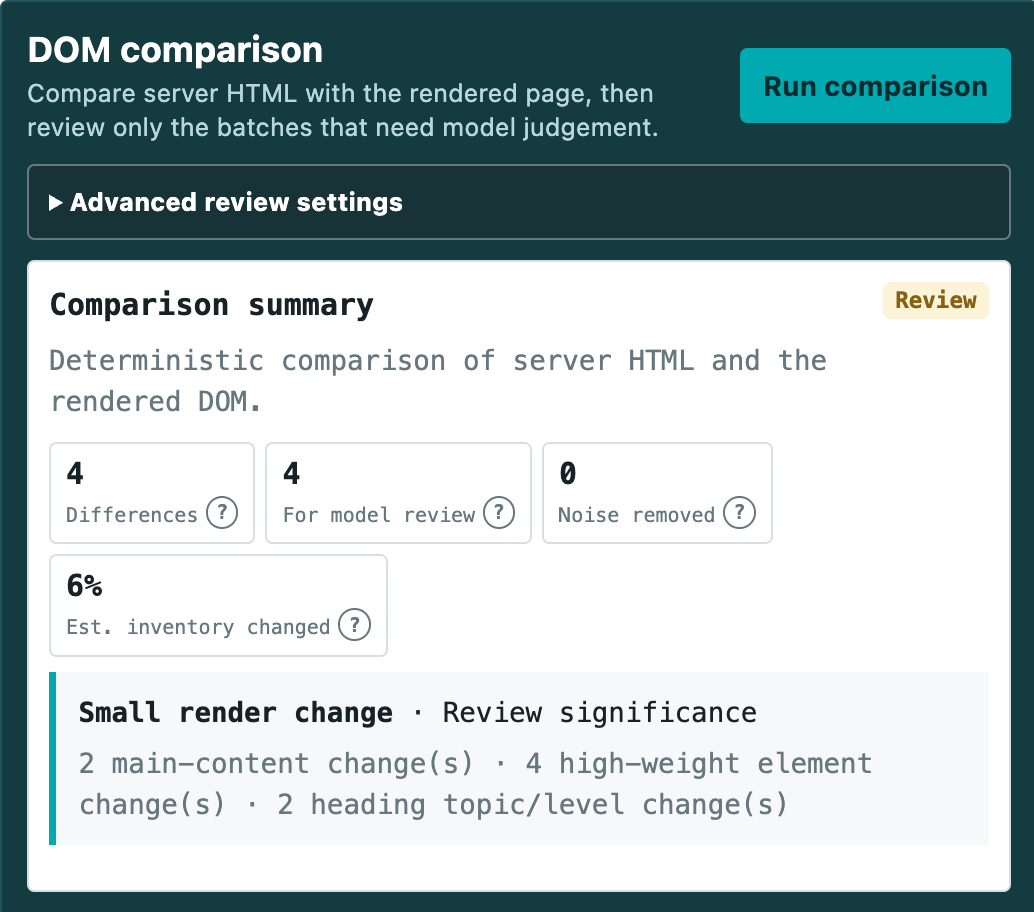
It is particularly useful for investigating JavaScript-heavy pages and questions such as:
did a heading disappear or change after rendering?
did a link destination change?
was content added or removed?
is a working URL only available after JavaScript?
how much meaningful page content actually changed?
The extension tries to reconcile likely before/after versions of the same element and remove obvious implementation noise rather than treating every generated ID or hydration-state change as meaningful.
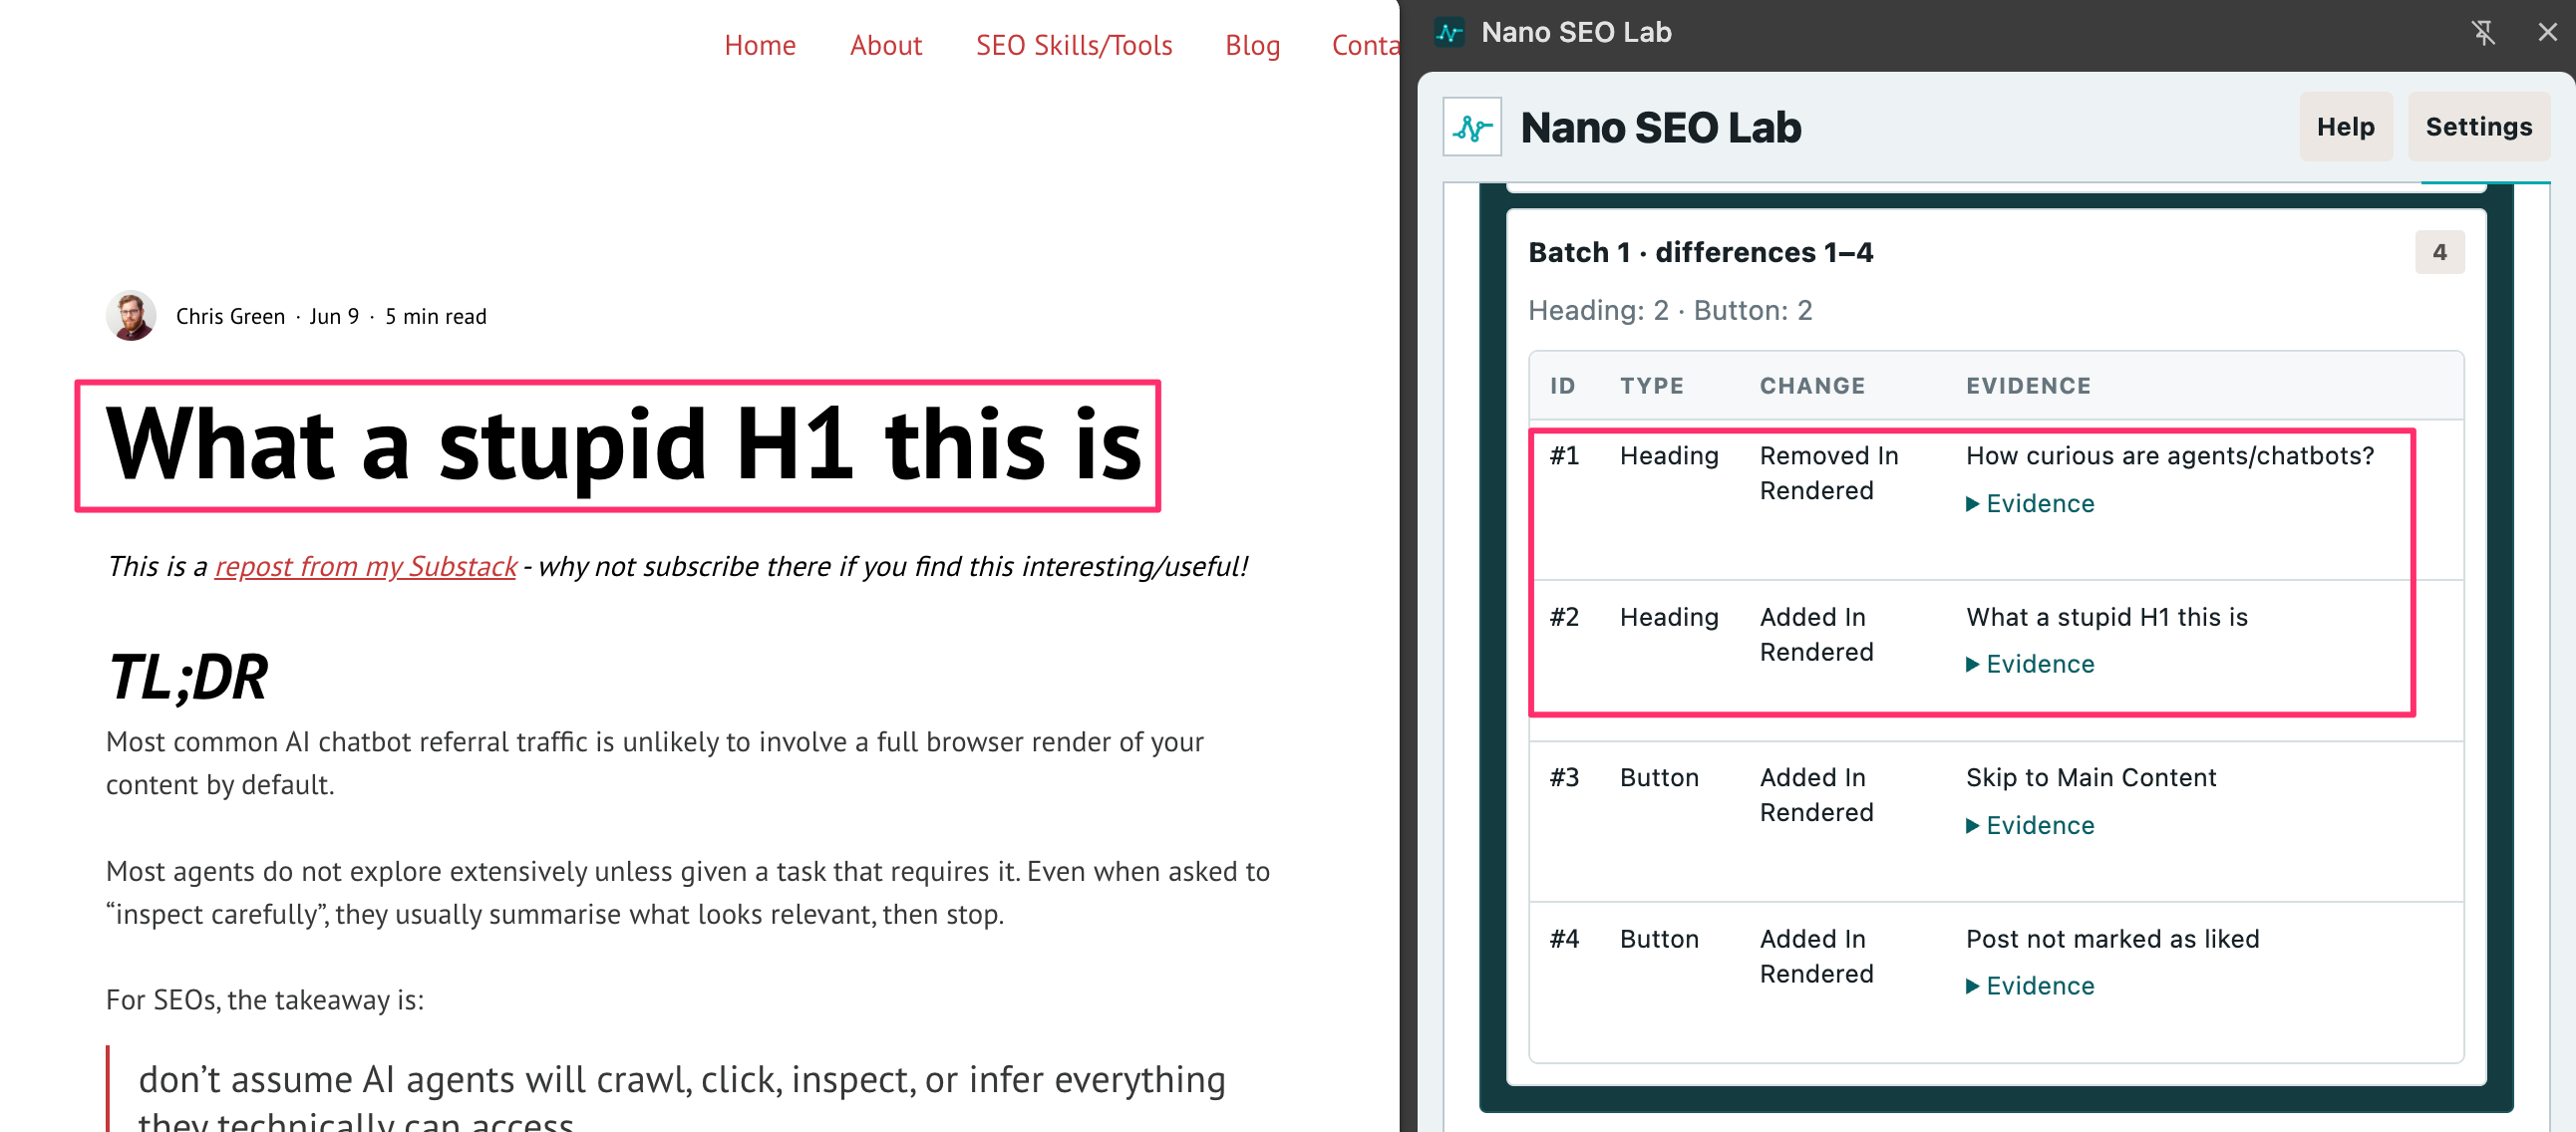
Any remaining differences that may benefit from interpretation are grouped into batches, and you can review whichever batches you want.
Under Advanced review settings you can change the model batch size.
There is also a Download unfiltered diff option. This exports the earlier stages of the comparison before the normal reconciliation/noise-filtering process, which is useful if you are debugging why something did or did not appear in the final comparison.
Out of all the tools in Nano SEO Lab, this is the one I need to stress test more and more. JavaScript can be tricksy and so can interpreting it for potential SEO/GEO impact. I am tweaking this a lot, but more feedback here would be great!
Check indexability signals
Check HTTP & robots signals performs the more network checks that I don’t want running automatically every time you inspect a page.
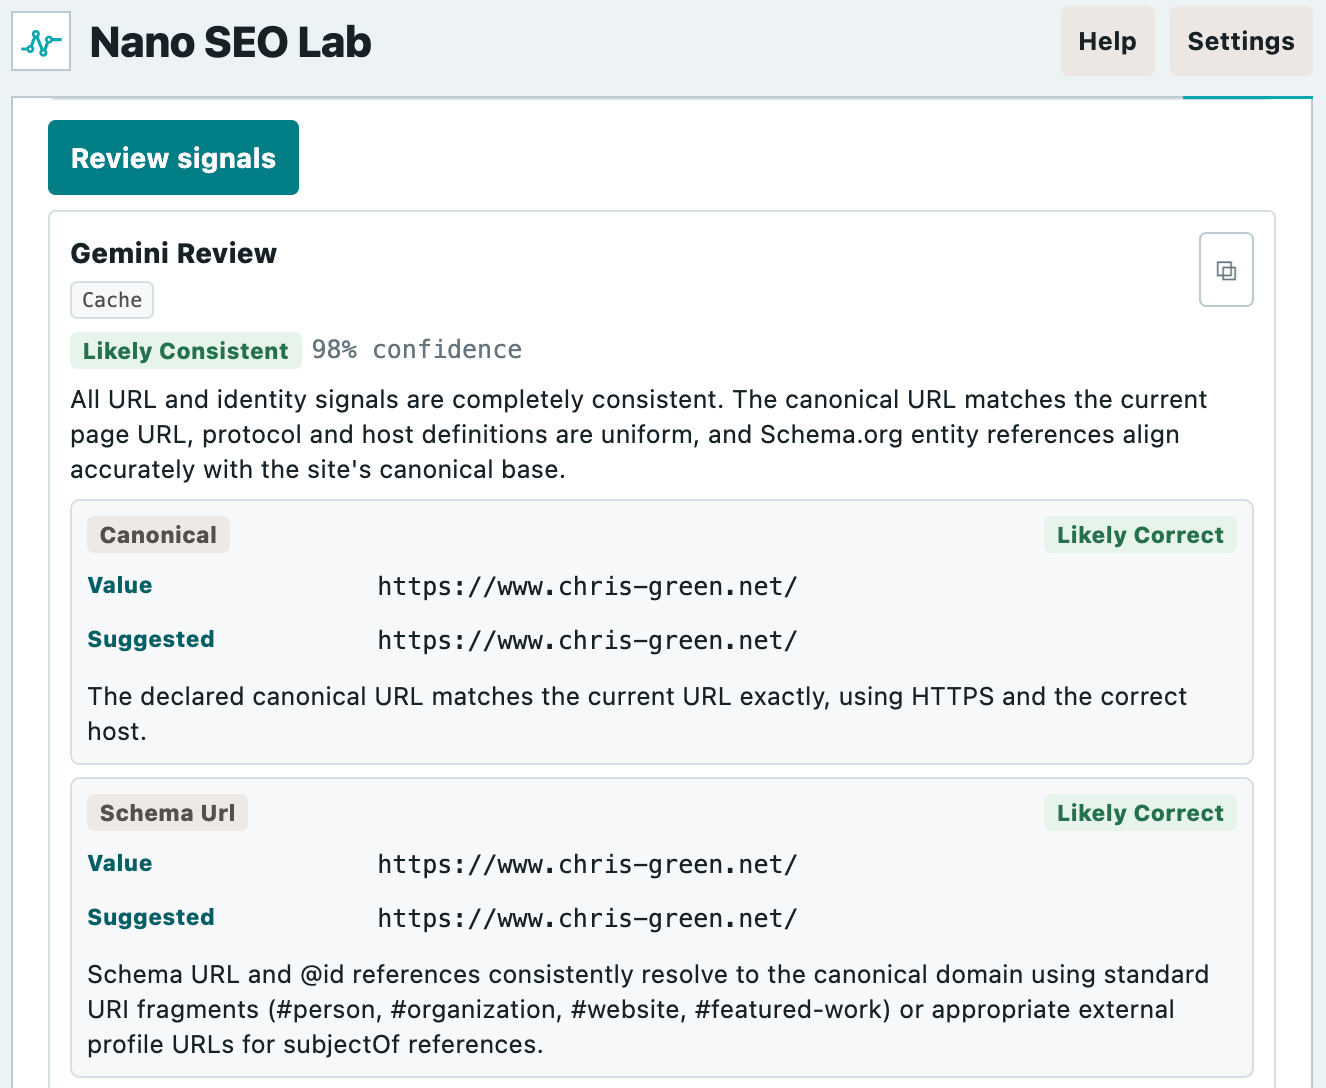
You control when it happens for predictability. With it you can compare things such as:
HTTP headers
server HTML directives
rendered directives
robots.txt
canonical targets
crawler access signals
Review URL and locale signals
This section pulls together things such as canonical and hreflang signals and looks for contradictions.
The hreflang validation itself is deterministic, while Review signals can be used when the overall combination needs some interpretation.
This is mostly useful for the awkward cases where each individual tag may look reasonable, but together they tell conflicting stories about what the page is supposed to represent.
History
The History tab is mostly there for inspection and research.
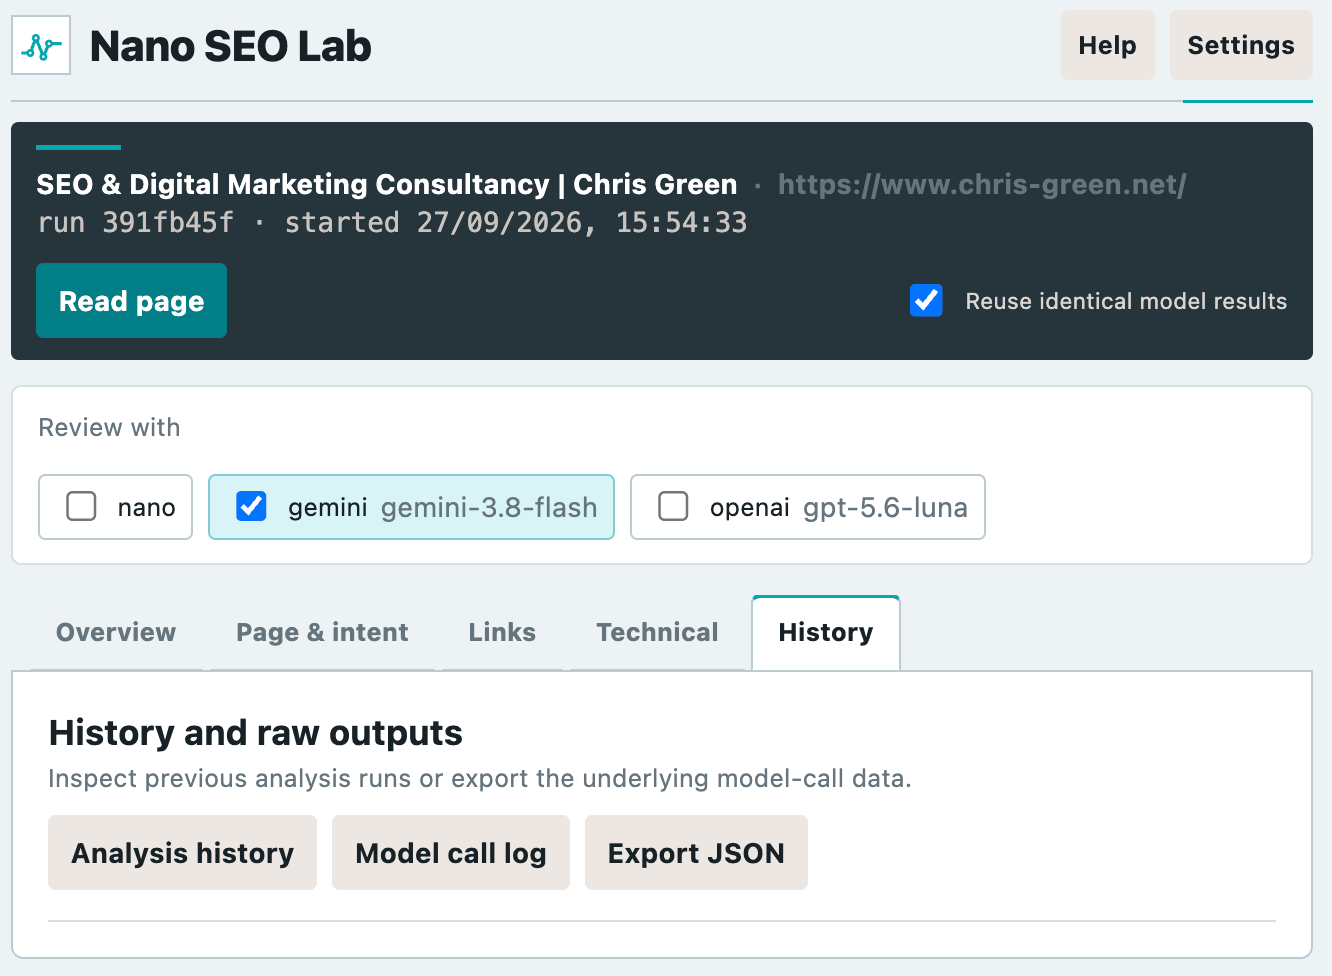
You can:
reopen previous analysis runs
inspect the model-call log
export the underlying JSON
I find this useful while developing and testing the extension, but it is also handy if you want to understand exactly what evidence was sent to a model rather than only looking at the final output.
If anything goes wrong and you want me to take a look, sending me the relevant log detail is super-helpful.
Where this fits in practice
I can see the extension becoming most useful for the small investigative actions that happen between larger pieces of SEO work. It won’t replace crawlers or analytics OR a skilled consultant. Instead, reducing the friction around questions like:
What’s actually happening on this page?
Is this change only happening after render?
Are these two URLs functionally the same?
What happens when these links are actually requested?
Is this finding worth investigating?
Can I turn this evidence into something useful for a developer?
This covers some of the most important page-level technical SEO/GEO questions. It does it without an over-reliance on AI, but rather - I hope - using AI where it makes the most sense, or is the most useful.
It's brilliant to see some of these tools flowing out from you, well done mate
Keeping deterministic checks separate from model interpretation matters operationally, because it gives a reviewer a defensible reason for every ticket that gets created. I’d pair that workflow with a simple severity-to-impact field so teams can prioritize issues tied to indexed pages, qualified entry points, or conversion paths rather than treating every discrepancy as equal. That would make the extension useful in the weekly backlog review, not only during audits.